|
THE GALTA NEWSLETTER
October 2026 · Issue 04
|
|
IN THIS ISSUE What a language score actually tells us • Editorial: why AI keeps failing at multiple choice • Members’ coffee hour, 13 October • Myriam Iliovits on EMI and validity, 26 October • Olena Rossi in November, with the member code • Glyn Jones on demand • Competition round 4 • Our 2027 conference • Research from the region
|
|
|
What Does a Language Score Actually Tell Us?
Christopher Hastings has never been an enthusiastic supporter of testing. Then he watched students who had struggled in his English classes present their research with confidence, and started asking what a score can and cannot show us about a learner.
|
FEATURE ARTICLE · 5 MIN READ |
 | Christopher Hastings Chair, English Department, Alfaisal University, Riyadh |
| | “A score is evidence, not the whole learner. The most useful assessment helps teachers understand what students can do, and it helps learners understand how to keep moving forward after they leave our classrooms.” |
Last semester, I volunteered to judge our Research Day Student Poster Competition, where students presented semester-long projects in engineering, medicine, and business. I recognized several students from my English classes. Some had performed very well in class; others had struggled with their writing assignments. However, when they discussed topics that mattered to them, they demonstrated a level of confidence and English proficiency that I had not always seen in their coursework. They were operating in their fields, not simply completing an English assignment.
This was reassuring, but it was also humbling. My classes supported what these students would eventually need to do, but the assessments I had seen showed only part of their abilities. They told me something real, but they did not show me the whole learner.
A confession about testing. It may be awkward to admit this in the GALTA newsletter, but I have never been an enthusiastic supporter of testing. I’ve often referred back to the saying, “one does not fatten a sheep by weighing it,” in framing my own discussions on the topic. Learning improves not by measurement alone, but by using evidence to inform teaching, feedback, and subsequent practice (Black & Wiliam, 2009).
Now that I have moved into administration, however, I recognize that we need evidence about our students, teaching, and programs. The question is not whether scores are useful, but what a particular score actually allows us to say.
What FSI taught me about scores. My own experience studying Arabic helped me reconsider this. While working for the State Department, I was enrolled at the Foreign Service Institute to study Arabic. Before studying there, I was skeptical of its highly contextualized approach. We joked that its students could speak about a nation's economy or political issues, but could not necessarily say they had had too much to eat. Once I entered the program, I understood the challenge differently. I appreciated how the teachers moved learners at different levels toward the professional tasks they would actually need to perform.
The assessment of my spoken Arabic was particularly helpful. It said that I could sustain paragraph-length speech, express opinions, and support ideas with examples, but the rater identified recurring problems with tense, word choice, gender agreement, and transitions. After years of studying Arabic, feeling that I was treading water, I had a clearer picture of where I was and where I needed to go. The assessment did more than assign me a level; it gave direction to my learning.
What this looks like in my classroom. That experience has shaped how I think about my own students at Alfaisal University. I have come to think of assessment less as a way to measure language in isolation and more as a way to create space for students to show what they can actually do in medicine, engineering, or business. In one multimodal assignment, students draft written material, revise based on feedback, record and refine their language, and present a polished, professional product. The process has reminded me of the learning that occurs from the first idea to the final performance, when students begin to make their development visible through authentic, discipline-based communication (Douglas, 2012).
If a student includes their first language in early drafts, I see it as part of the thinking process. This is the translanguaging approach that treats their full linguistic repertoires as resources for meaning-making, although the process is difficult to capture in a conventional English test (García & Wei, 2014; Li, 2018).
Where AI fits, and where it does not. Large classes and limited faculty time make detailed formative assessment difficult. This is one area where AI has helped me. I can collect short responses through Microsoft Forms and use AI to identify class-wide patterns and representative examples. Across a collection of papers, it helps me notice recurring needs that I might miss while grading one student at a time. AI helps me process evidence, but it should not decide what counts as evidence.
What a score cannot tell you. Watching my students present their research did not prove that their classroom assessments were wrong. It reminded me that those assessments showed only part of what they could do. As teachers, we should remain humble about what our assessments allow us to see. A score is evidence, not the whole learner. The most useful assessment helps teachers understand what students can do, and it helps learners understand how to keep moving forward after they leave our classrooms.
REFERENCES Black, P., & Wiliam, D. (2009). Developing the theory of formative assessment. Educational Assessment, Evaluation and Accountability, 21(1), 5–31. https://doi.org/10.1007/s11092-008-9068-5 Douglas, D. (2012). ESP and assessment. In M. H. Long (Ed.), The handbook of English for specific purposes (pp. 367–383). Wiley-Blackwell. García, O., & Wei, L. (2014). Translanguaging: Language, bilingualism and education. Palgrave Macmillan. Li, W. (2018). Translanguaging as a practical theory of language. Applied Linguistics, 39(1), 9–30. https://doi.org/10.1093/applin/amx039
|
ABOUT THE AUTHOR Christopher Hastings is Chair of the English Department at Alfaisal University, an applied linguist and international educator, and a former U.S. Department of State Regional English Language Officer. His work explores the intersections of language, communication, education, and culture through teaching, research, professional training, and international collaboration. |
|
|
VIRTUAL MEMBERS’ COFFEE HOUR · CASUAL · BRING A MUG
AI and item writing: what is it actually good for?
A meetup, not a webinar. No slides, no recording, no agenda beyond the editorial below. Bring the items you tried to write with generative AI, the prompts that worked, the ones that produced nonsense, and the item you had to cancel. Cameras optional, coffee mandatory.
|
|
TUE 13 OCT · 7 PM KSA · 8 PM UAE |
|
|
|
READ AND WATCH BEFORE WE MEET
READ Rossi, Brunfaut & Harding (2025). What makes item-writing training useful? Studies in Language Assessment, 14(1). Read it →
WATCH “Item Writing for Assessment”, Educational Assessment ep. 6, University of Oxford Department of Education. Watch it →
|
Want this to outlive one Tuesday? Five members, a convener and an idea are all it takes to start a GALTA Special Interest Group. |
|
|
|
EDITORIAL · FROM THE EDITORIAL BOARD · 4 MIN READ |
|
The Problem Is Not the Students
23% of the distractors in ChatGPT-written reading items did any work; the rest were dead weight |
|
2,267 test-takers checked GenAI’s revised listening distractors; it still missed how learners mishear |
|
50 teachers could not fault ChatGPT’s reading passages, but still preferred the human-written options |
|
Ask any of us which part of item writing is hardest and nobody says the passage. It is the question, and above all the four short lines under it. A multiple-choice item looks like the easiest thing on the paper. Most of us learned the hard way that it is the hardest to get right.
The stakes are not abstract. In a preparatory-year programme or a high-school final, the grade decides who passes, and every item carries a piece of that decision. Run the item analysis on almost any teacher-written exam and you will find distractors nobody chose. They are furniture.
You know the pattern from your own item analysis. Three hundred students sit the exam. On item 17 the answers are spread evenly across A, B, C and D, or split neatly between two options. Nobody teaches so badly that three hundred people guess at random. The problem is not the students. The problem is the item, and one of us wrote it.
AI was supposed to rescue us here, and it keeps failing at exactly this point. Li and colleagues (2026) gave 121 test-takers ChatGPT-written reading items in the style of China’s CET-4 exam, alongside the official ones. The generated items were easier, separated strong and weak students less well, tested lower-order skills, and only 23% of their distractors did any work at all. A plausible wrong answer requires knowing what a learner at that level actually confuses. Wang and Meng (2026) hit the same wall from the other side: with experts steering it and 2,267 test-takers checking it, generative AI improved the distractors in a listening test but could not capture the ways learners actually mishear, which is what makes a listening distractor work. We know those ways; we have marked the papers. The model has not.
| | That is the thing about AI output: it looks good. |
The uncomfortable part is about us, not the machine. Fifty Korean teachers rated ChatGPT’s reading passages without knowing who wrote them and found them as natural as the national exam’s. Only on the answer options did the human writers win (Shin & Lee, 2023). Sixteen Japanese instructors could not tell ChatGPT’s JLPT-style items from an expert’s, except, again, on the answer choices (Dizon & Kurose, 2026). That is the thing about AI output: it looks good. So you write the exam with AI, a colleague reads it on the train, says it is fine, and out it goes. Then item 17 splits the year down the middle, the item is cancelled, the exam is rescaled, and you spend an afternoon explaining to three hundred students and a dean why the pass mark moved. A colleague’s read-through catches typos. The students catch the rest, and by then it is expensive.
None of this is an argument against the tool. It is an argument for knowing more than the tool does. Writing options that discriminate is a craft, and crafts are learned from people who practise them. Olena Rossi has spent her career doing exactly that, and her four Saturdays in November are the closest thing to an apprenticeship you will find. Forty seats, live only; details below.
Before that, bring your item 17 to the members’ coffee hour on Tuesday 13 October at 7 pm KSA. We want the stories: the question that looked perfect on Sunday and was cancelled on Thursday, the option half the class chose for a reason nobody anticipated, the rescaling that ate a weekend. They might have been disasters in the moment, but they are now lessons learned and experience gained, and on Zoom, with coffee, the rest of us get them for free. Or write it down: Round 4 wants 500 words on this; details below.
REFERENCES Dizon, G., & Kurose, R. (2026). An exploratory comparison of ChatGPT-generated and human-made Japanese reading comprehension test items. Language Education & Assessment, 9 (open access). Li, B., Qin, Q., Li, W., & Mao, C. (2026). Psychometrics and linguistics in ChatGPT-generated reading tests compared with CET-4. Journal of Psychoeducational Assessment. doi.org/10.1177/07342829261444828 Shin, D., & Lee, J. H. (2023). Can ChatGPT make reading comprehension testing items on par with human experts? Language Learning & Technology, 27(3), 27–40. doi.org/10.64152/10125/73530 Wang, Y., & Meng, Y. (2026). Optimizing distractor quality in a locally developed second language listening test: Integrating generative AI and psychometric methods. Language Testing. doi.org/10.1177/02655322251400375 |
|
COMING UP |
|
THIS MONTH · FREE WEBINAR FOR MEMBERS · 26 OCTOBER
Language Use and Implications for Validity in an EMI University
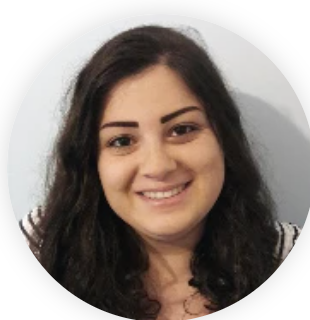 | Dr Myriam Iliovits University of Chester, UK · PhD in Language Testing, Lancaster University |
Most EMI universities outside English-dominant countries admit students on the strength of an English language test, yet very little research has asked how far those tests reflect the language students actually use once they arrive. Dr Iliovits studied language use at the American University of Beirut and discusses what her findings mean for the validity of admissions tests, in Lebanon and across our region.
Monday 26 October · 8:00 pm KSA (9:00 pm UAE) · 60 minutes on Zoom · Free for members
|
|
|
EDITORIAL PICK 40 SEATS · BOOKING CLOSES 5 NOVEMBER
Using Generative AI in Item Writing
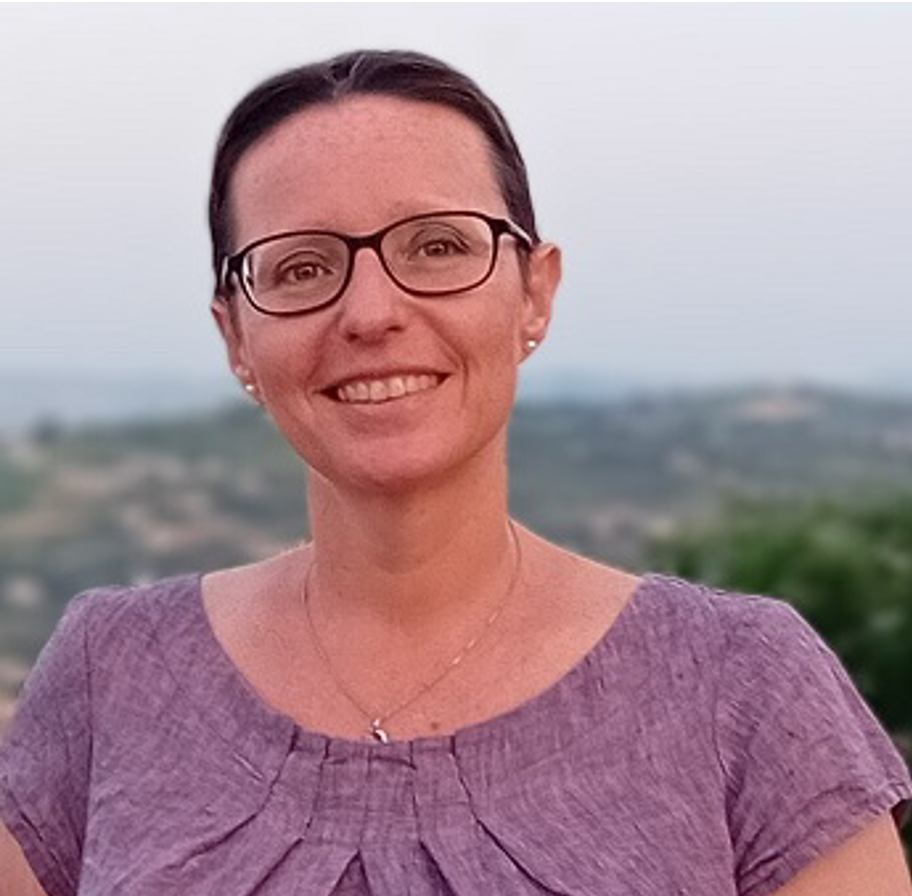 | Dr Olena Rossi PhD in Language Testing, Lancaster University · Founding convenor, EALTA AI in Language Assessment SIG |
Live only, no recordings: sixteen hours of hands-on training across the full item-writing cycle, from prompt design and reading and listening items to AI-generated audio and speaking tasks, and the judgement to evaluate, revise, or reject what the machine produces. The editorial above explains why that judgement is the whole point.
+ Optional practical strand: weekly tasks with individual feedback from Olena and structured peer review. 20 places, course holders only.
DATES Sat 7 · 14 · 21 · 28 November |
FORMAT 4 live sessions · 12:30–16:30 KSA · Zoom |
MEMBERS FROM £150 · SAR 760 |
|
MEMBER ACCESS CODE
THEKEY
Click “Enter access code” on the ticket page and the member prices appear.
|
|
|
|
SAVE THE DATES · OUR FIRST INTERNATIONAL CONFERENCE
Whose Evidence Counts?
Validity, Fairness, and Context in Language Assessment
Three days, fully online, on what happens when tests and frameworks built elsewhere meet the multilingual realities of our region, in Arabic, English, and Chinese. Papers, posters, and hands-on workshops: 250-word abstracts, reviewed anonymously, open now.
DATES 29 April – 1 May 2027 |
ABSTRACTS BY 15 January 2027 |
FORMAT Fully online · Zoom |
|
|
 |
NOW ON DEMAND · MEMBERS ONLY
Can We Trust the Levels? (Re)calibrating the CEFR Descriptors
Dr Glyn Jones spoke to members on 22 September about what held up when he replicated the CEFR research with 471 teachers in 45 countries. Missed it? The recording is in the members’ webinar library.
|
|
|
MEMBER COMPETITION · ROUND 4
The item that failed you
Round 4 asks for your sharpest 500 words on item writing: the item that fell apart in the analysis and what it taught you, the distractor that outperformed the key, or the case for writing them yourself in the age of AI. Your angle, your experience, and 500 is a hard ceiling.
The winning piece is published in the November issue, and the writer earns one free workshop session of their choosing.
DEADLINE: 25 OCTOBER
|
|
|
RESEARCH FROM THE REGION
|
Can AI rank Arabic essays as well as an expert?
Alzarahni, A., Alshumrani, H., & Alfaifi, A. (2026). Language Testing in Asia (open access).
The method is simple: show a judge two essays, ask which is better, repeat many times, and let the pairs build a ranking. Three Saudi researchers tried it on 90 Arabic essays with four kinds of judge: assessment experts, paid crowd workers, fellow students and GPT-4o. Experts, crowd and AI produced consistent rankings that matched conventional scores; the students did not. Comparative judgement works for Arabic writing, and who judges matters more than how many.
|
|
Online exams: the same three complaints everywhere
Al Fraidan, A. A., et al. (2026). Computer Assisted Language Learning.
Technical disruptions, awkward interfaces and the anxiety of a countdown timer: if your students say it, so do everyone else’s. A survey of 389 students, 42 faculty and 7 administrators at King Faisal University found exactly those three, alongside real appreciation for speed and instant feedback. The data also say what helps, and it is not fewer complaints but better preparation: mock exams, tutorials and a more intuitive, usable interface predicted positive attitudes; the obstacles themselves did not.
|
|
Writing is the hardest part of EMI. Now there are numbers.
El-Dakhs, D. A. S., Ibrahim, N. G., & Alenezi, A. (2026). Asian-Pacific Journal of Second and Foreign Language Education (open access).
No teacher in the region will be surprised, and that is the point: what we have known from the classroom now has data behind it. A survey of 217 undergraduates at a private Saudi university, with 16 interviews, found academic writing the most demanding skill by a clear margin. Prior EMI schooling and gender made a difference; discipline and year of study did not. Evidence to cite the next time writing support is on the agenda.
|
|
THE COMMUNITY
|
Join the WhatsApp community
Announcements, event reminders, and conversation with assessment colleagues across the region, between issues of this newsletter.
|
|
Share your news
New article, award, talk, or role? A title, a sentence, and a link is all it takes, and the region’s assessment community reads your name in the next issue. Email news@galta.org. Deadline for the November issue: 25 October. |
|
Start a Special Interest Group
Five members, a convener and an idea are all it takes. Your SIG gets a standing spot in this newsletter, a board liaison and an events platform.
|
|
|
|
Know someone who should be reading this?
Forward this issue to a colleague. Membership is currently free, and it comes with events, recordings, tools, and the regional community.
|
|
Gulf Association for Language Testing and Assessment
|
|
|